Creating a RAG Topic — Step by Step
You create a Topic in a five-step wizard. Open RAG Topics in the menu and click New Topic.
You need the TOPIC_CREATE permission.
The stepper at the top shows the five steps:
| Step | Name in the stepper | Subtitle |
|---|---|---|
1 |
Common Info |
Name & Description |
2 |
Model Strategy |
Embedding & LLM |
3 |
Vector DB |
Vector Storage |
4 |
Retrieval Strategy |
Reranking & Filtering |
5 |
Datasources |
Data & Chunking |
Next checks the current step before it moves on. Back goes one step back. You can also click the name of a step you have already passed to go back to it. Steps ahead of you cannot be clicked, so no check is skipped. On step 5 the button reads Save.
Before you start
Have these ready, otherwise you get stuck in the middle of the wizard:
| Needed | Where it comes from |
|---|---|
An AI server with a language model (chat model) |
Admin → AI Servers — see AI Servers |
An AI server with an embedding model |
The same server or another one |
A Docling server, if you want to upload PDF, DOCX or PPTX files, or allow them as chat attachments |
Admin → Docling Servers — see Docling Servers |
A vector database — required |
Admin → Vector Databases — see Connect Vector DB |
A free port on the server for this Topic |
Any port that no other Topic or program uses |
You also need a valid license (Admin → License). Without one, or when the license’s Topic limit is reached, a message appears when you click New Topic, and the wizard does not open. The same check runs again when you click Save. The messages are, for example:
-
There is no valid license. Enter a license key under Admin → License, or contact cyrock.ai.
-
You have reached the limit of your license: 3 of 3 topics. Delete one, or contact cyrock.ai to upgrade your license.
Step 1 — Common Information
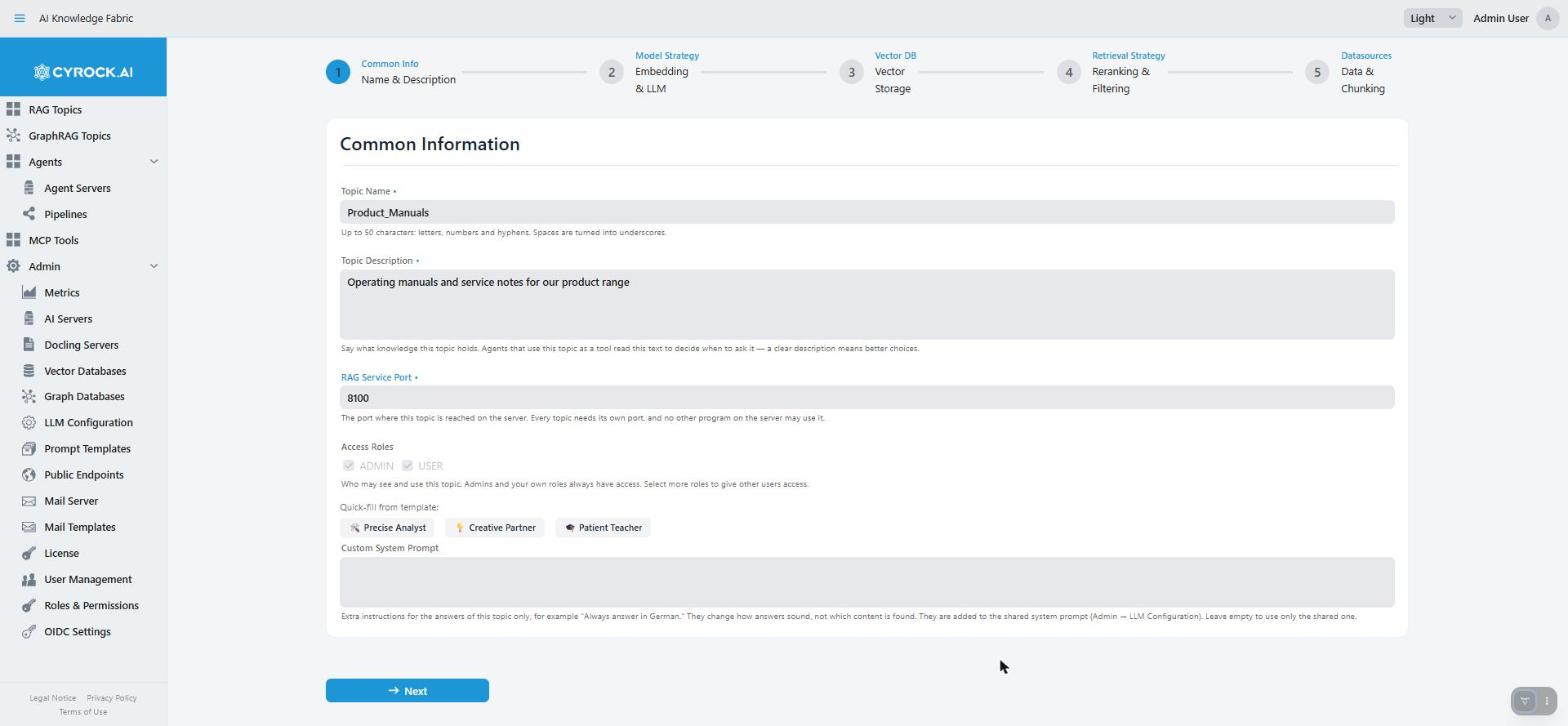
| Field | Required | Notes |
|---|---|---|
Topic Name |
Yes |
Up to 50 characters. Letters, numbers, hyphens and underscores. Spaces turn into underscores while you type. Must be unique |
Topic Description |
Yes |
What knowledge this Topic holds |
RAG Service Port |
Yes |
A number from 1 to 65535 |
Access Roles |
— |
Who may see and use the Topic |
Custom System Prompt |
No |
Extra instructions for the answers of this Topic |
Messages you can see on this step:
-
A topic with this name already exists
-
Name may only contain letters, numbers, hyphens and underscores; other special characters are not allowed
-
RAG Service Port is required
-
Port must be between 1 and 65535
Topic Description
Say clearly what knowledge the Topic holds. Agents that use this Topic as a tool read this text to decide when to ask it. A clear description means the agent picks the right Topic more often.
RAG Service Port
The port where this Topic is reached on the server. It also makes the REST interface reachable. Every Topic needs its own port, and no other program on the server may use it. The wizard does not check this. A port that is already taken shows up only when you start the Topic. Pick a simple scheme you can keep track of, for example 8081, 8082, 8083.
Access Roles
Only the roles you tick here can see and use the Topic. This works on top of the TOPIC_VIEW
permission — see
Roles & Permissions.
The ADMIN role and your own roles are always ticked and cannot be unticked. So you never lock yourself out of a Topic you created. Tick more roles to give other users access.
Custom System Prompt
Here you give the Topic its own instructions, for example "Always answer in German." or "You are an HR assistant. Cite the section you used." These instructions change how answers sound. They do not change which content the search finds. Leave the field empty to use only the shared system prompt.
Your text is added to the shared system prompt (Admin → LLM Configuration). So you don’t need to repeat general rules, only what is special for this Topic. See Global LLM Configuration.
Above the field, Quick-fill from template: shows one button per prompt template from Admin → Prompt Templates. A click replaces the content of the field with the template. So pick a template first and edit it afterwards. The buttons only appear when at least one template exists.
The other texts of the Topic — for example the shared system prompt for this Topic only, or the instructions of single model steps — are on the Topic’s Prompts tab after creation. See Prompts.
Step 2 — Model Strategy
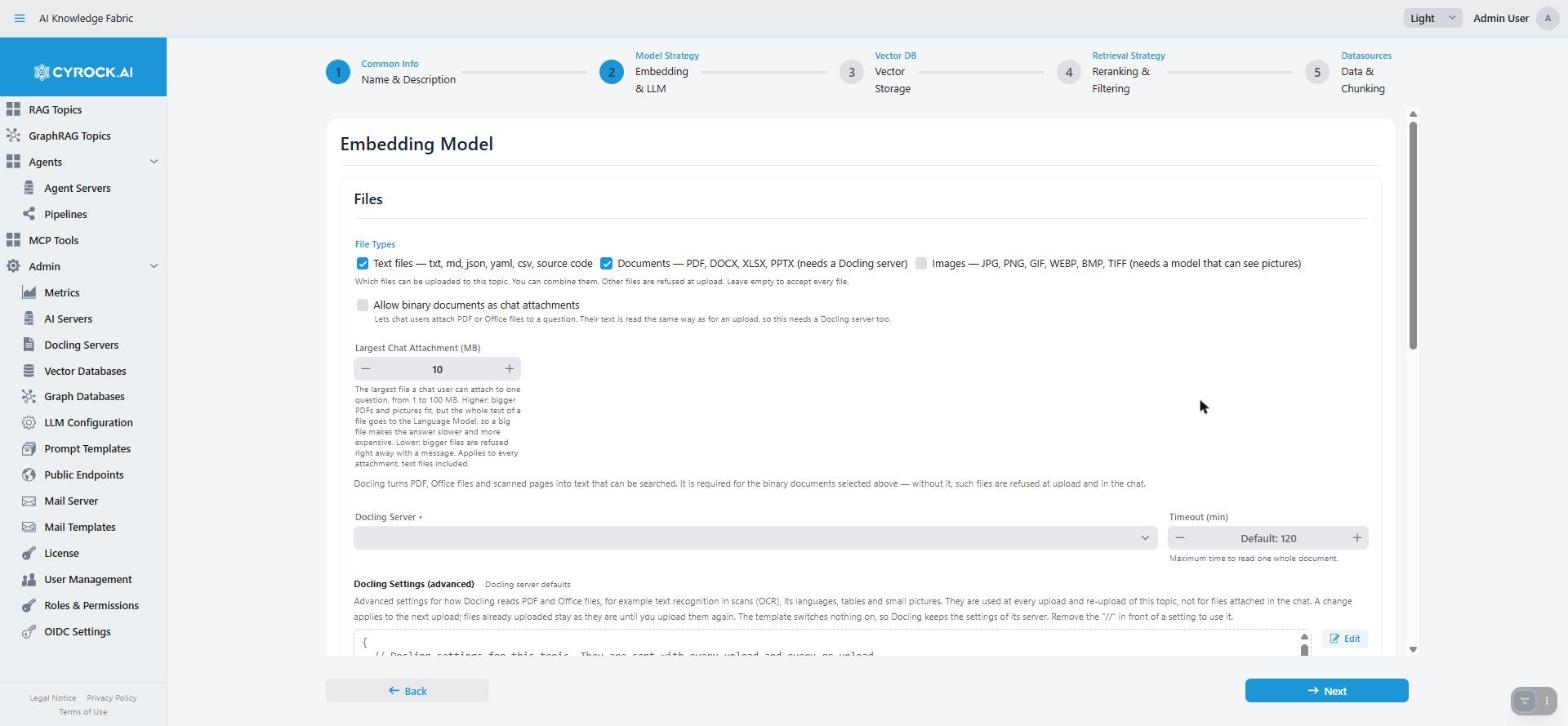
The largest step. From top to bottom it has these parts:
-
Files — which files can be uploaded, plus Docling
-
Structured Data Import
-
Image Handling — pictures in documents, and images as chat attachments
-
Embedding Model
-
Large Language Model (shown as Language Model)
The step adapts to the File Types you tick first. Next only works when an embedding model and a language model are both selected. If something is missing, a red message appears under the part that needs it. Scroll down to see it.
Choosing a model
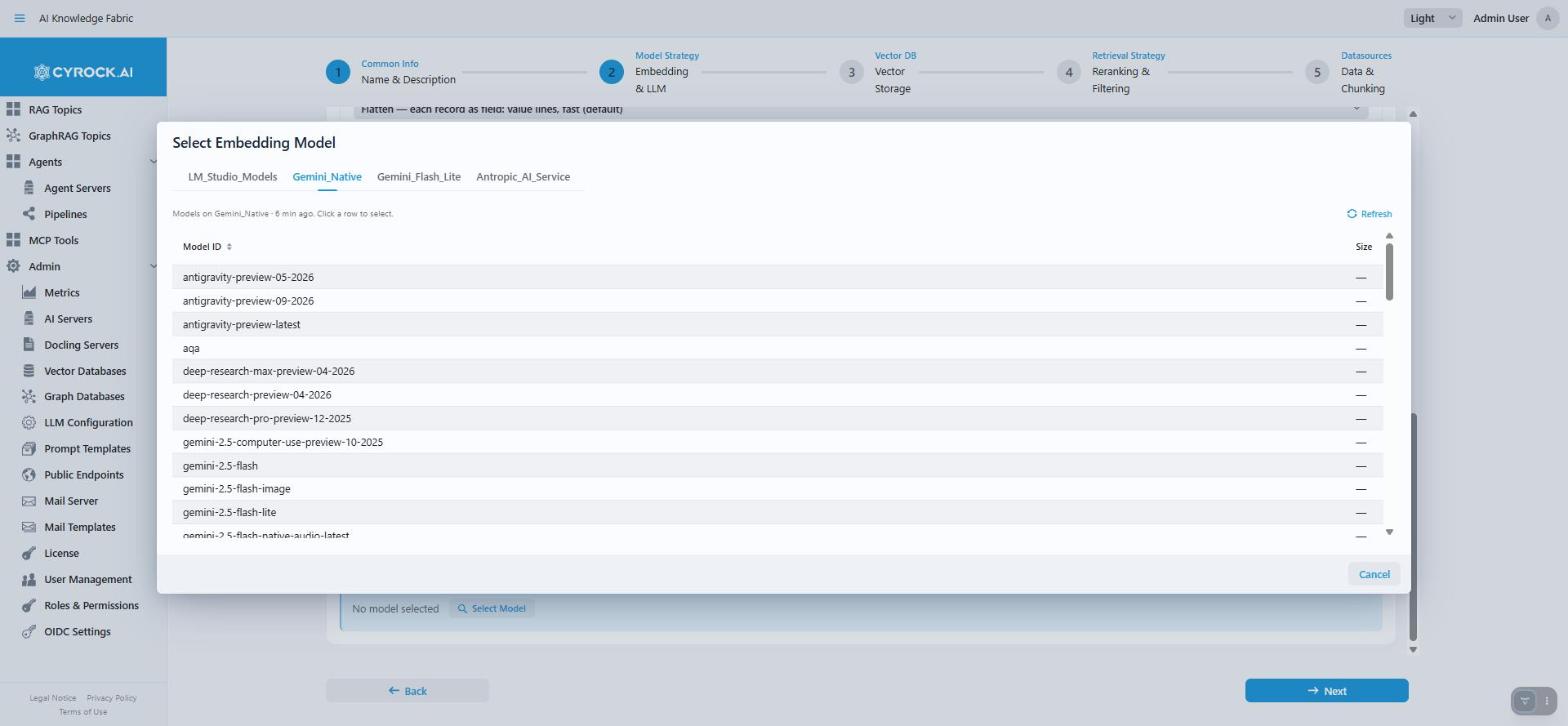
Each Select Model button opens a dialog with one tab per AI server. The list comes from a stored copy of each server’s model list. So the dialog opens fast, even when a server is slow. The line above the list says how old the list is, for example Models on MyServer · 4 min ago. Click a row to select. Click Refresh to get the list from the server again, for example after you installed a new model.
-
If the server cannot be reached but a list was loaded before, the dialog shows the older list with a note Could not refresh ….
-
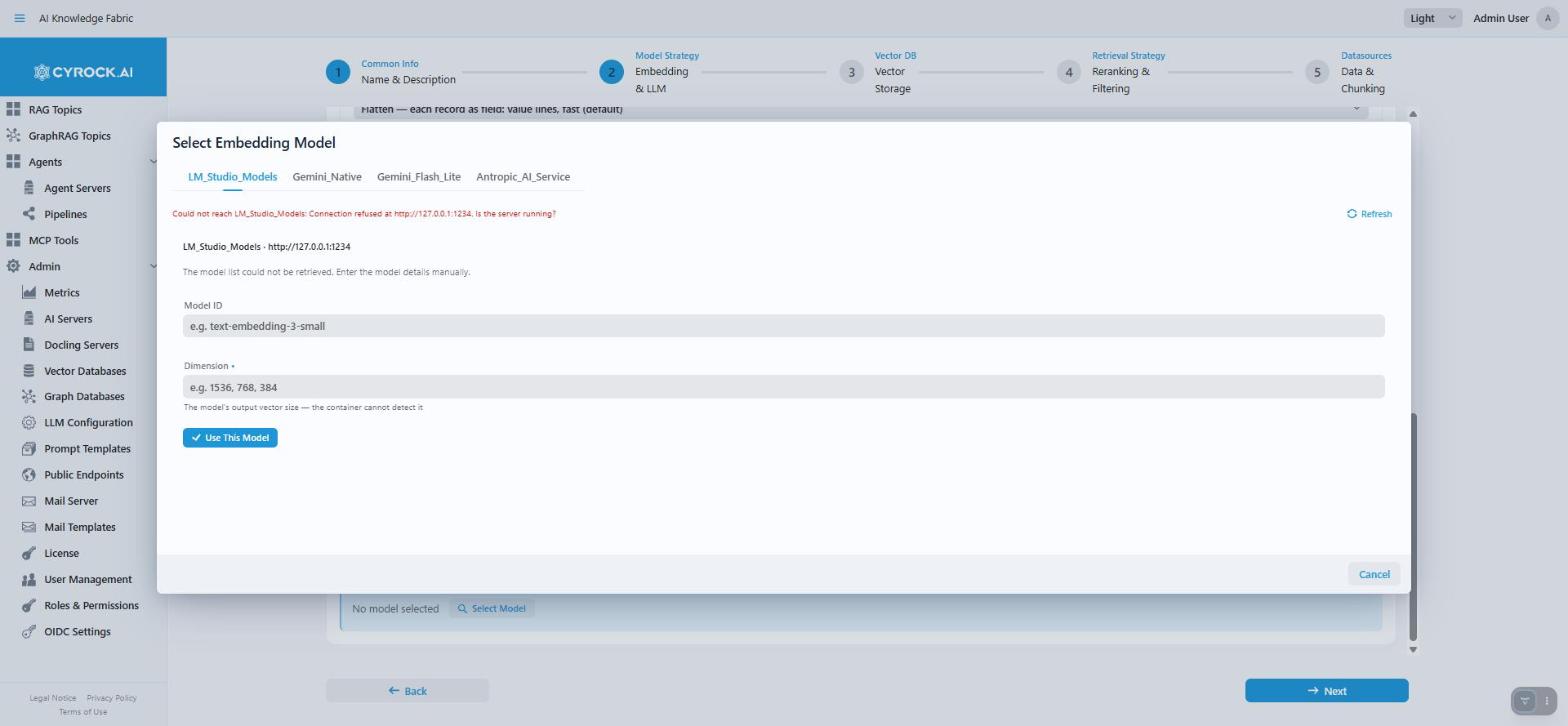
If no list is available at all, the dialog says The model list could not be retrieved. Enter the model details manually. Type the Model ID and click Use This Model.
After a choice, the button reads Change, and the selection shows as server ─ model.
Files
| Field | Default | Notes |
|---|---|---|
File Types |
none ticked |
Text files, Documents (PDF, DOCX, XLSX, PPTX — needs a Docling server), Images (needs a model that can see pictures). You can combine them |
Allow binary documents as chat attachments |
off |
Lets chat users attach PDF or Office files to a question |
Largest Chat Attachment (MB) |
10 |
The largest file a chat user can attach to one question, 1–100 MB. Higher: bigger PDFs and pictures fit, but the whole text of a file goes to the Language Model, so a big file makes the answer slower and more expensive. Lower: bigger files are refused right away with a message. Applies to every attachment, text files included |
File Types decides which files the Topic’s Data Upload tab accepts. Other files are refused at upload. If you leave all boxes empty, every file is accepted. Ticking the types that match your content gives you a clear message at upload instead of a failed upload later.
The choice also changes the rest of this step:
-
Documents ticked → the Docling part appears (see below).
-
Images ticked → Describe pictures with a vision model is switched on and locked, and a hint suggests a multimodal embedding model.
-
Only Images ticked → the Structured Data Import part is hidden.
Docling
Docling turns PDF, Office files and scanned pages into text that the search can use. The part appears as soon as Documents is ticked among the File Types, or Allow binary documents as chat attachments is ticked. Without a Docling server such files are refused, at upload and in the chat.
| Field | Notes |
|---|---|
Docling Server |
Required while this part is visible. Lists the servers from Admin → Docling Servers |
Timeout (min) |
How long the Topic waits for Docling to read one whole document (1–120). Empty uses the global default from Admin → LLM Configuration, shown in the field |
Docling Settings (advanced) |
Optional settings for how Docling reads files |
Without a server, the message Select a Docling server — binary formats cannot be read without one. appears.
Timeout (min): a higher value lets long scanned PDFs finish; without a graphics card they can take minutes. A lower value lets a stuck upload fail sooner. If the value is longer than the server’s own Max Conversion Time (Admin → Docling Servers), a warning says so: that server stops first, so the longer timeout has no effect. Raise the limit on the server instead.
Docling Settings (advanced): a text with settings in JSON form, for example text recognition in
scans (OCR), its languages, tables and small pictures. Click Edit to open the editor. The template
switches nothing on, so Docling keeps the settings of its server. Remove the // in front of a setting
to use it. Apply takes the settings into the wizard. The settings are used for every upload of this
Topic, not for files attached in the chat. A misspelt setting name is not reported — Docling ignores it.
The line above the preview says Docling server defaults or Customised for this topic.
Structured Data Import
Applies to structured files: JSON, XML, YAML, TOML, CSV and TSV. They are recognized by their file ending. They are always split into records — for example one table row each — so a record is never cut in the middle.
| Field | Options | Notes |
|---|---|---|
Import Strategy |
Flatten (default) · Narrate |
How each record is stored during upload |
Narrator Model |
only with Narrate |
The model that rewrites the records |
-
Flatten stores each record as
field: valuelines. Fast. Good for questions that use the exact field names or values. -
Narrate lets a model rewrite each record as a short paragraph. Questions in normal language find it better. But large files take much longer, because each record needs one model call.
The Narrator Model shows Reuses chat LLM until you pick one. Then the Topic’s Language Model does the work. A small, fast model keeps large uploads short. Reuse Chat LLM removes your pick again.
Image Handling
This part has two separate topics: pictures that arrive during upload, and images that users attach in the chat.
Pictures in documents and uploaded pictures:
| Field | Default | Notes |
|---|---|---|
Describe pictures with a vision model |
off |
Always on, and locked, while Images is a File Type |
Store pictures in the database |
on |
|
Show pictures in answers |
on |
Only available while Store pictures in the database is on |
-
Describe pictures with a vision model — On: during upload, a vision model describes each picture. The description is placed in the text where the picture was. So the content of pictures can be found, but uploads are slower. Off: only the picture’s caption can be found. An uploaded image file has no text of its own. Without a description the search never finds it. That is why the box is locked on while Images is a File Type.
-
Store pictures in the database — On: each picture is kept, so an answer can show it and name it as a source. This needs more storage. Off: the answer names only the document.
-
Show pictures in answers — On: answers can show stored pictures in the text and list them below. Off: answers are text only. This affects only the chat, so you can change it later without uploading again.
When Describe pictures with a vision model is on, three more fields appear:
| Field | Notes |
|---|---|
Image Describer Model |
The model that describes each picture during upload. It must be able to read images. A larger model sees more details, but makes uploads slower |
Use the topic’s Language Model |
Tick this instead of picking a model. Then the Language Model (further down) describes the pictures. It must be able to read images |
Picture Description Timeout (minutes) |
Maximum time to describe one picture (1–120). Higher lets slow models finish. Lower lets a stuck upload fail sooner. Empty uses the global default from Admin → LLM Configuration |
You must either pick a model or tick Use the topic’s Language Model. Otherwise the message Select a model to describe images, or tick the box to use the topic’s Language Model. appears. With the box ticked, you must also pick the Language Model below, otherwise the message is Pick the topic’s Language Model below before inheriting it here.
Images in the chat:
| Field | Default | Notes |
|---|---|---|
Allow images as chat attachments |
off |
Lets chat users attach images to a question |
An attached image goes directly to the Topic’s Language Model, not to the Image Describer Model, which works only during upload. So the Language Model must be able to read images. Nothing checks this for you.
Chat attachments — summary
Which files users may attach to a chat message is decided on this step:
-
Text files can always be attached.
-
PDF and Office files only when Allow binary documents as chat attachments is on (in Files). This needs a Docling server.
-
Images only when Allow images as chat attachments is on (in Image Handling). The Language Model must be able to read images.
-
Each file may be at most Largest Chat Attachment (MB) large (in Files, default 10 MB).
Embedding Model
The embedding model turns each text piece and each question into numbers. That way the search finds text with the same meaning, even when it uses other words. A better model finds better matches, but makes uploads slower.
|
The embedding model cannot be changed after the Topic is created. For another model, create a new Topic. |
When Images is a File Type, a hint says This source type usually needs a multimodal embedding model.
Dimension. Each embedding model produces a list of numbers of a fixed length, the dimension. The Topic must know it. What happens after you click a model depends on the server:
-
Ollama server: the dimension is found automatically. No question is asked.
-
Other servers: a dialog Embedding Dimension shows the size the model produces, in the field Dimension. Some models can produce fewer numbers. A smaller value needs less storage and makes the search faster, but slightly less exact. Leave the value as it is to use the full size. A smaller value is tested with the model right away; if the model refuses it, the dialog says so.
-
Size not found: the dialog asks you to enter the dimension. You find it in the model’s documentation.
-
Manual entry (no model list): enter Model ID and Dimension together. Both are required.
The dimension is required. Without it, the Topic could not start. The selection shows it after the
model name, for example (768d). Messages you can see:
-
Please select an embedding model and a server
-
Enter the embedding model’s output dimension
-
The embedding model has no dimension — select it again and enter one
Large Language Model
The Language Model writes the chat answers from the text pieces the search found. It also does the other model steps of this Topic unless they have their own model — for example narrating records, describing pictures (when inherited), sorting results (reranking), routing and writing keywords. A larger model gives better answers, but is slower and costs more.
Check two things:
-
Tool calling, if you want to connect MCP tools later. A model without it ignores them.
-
Reading images, if you tick Allow images as chat attachments or Use the topic’s Language Model for pictures.
Without a model, the message Please select a language model and a server appears.
Step 3 — Vector Storage
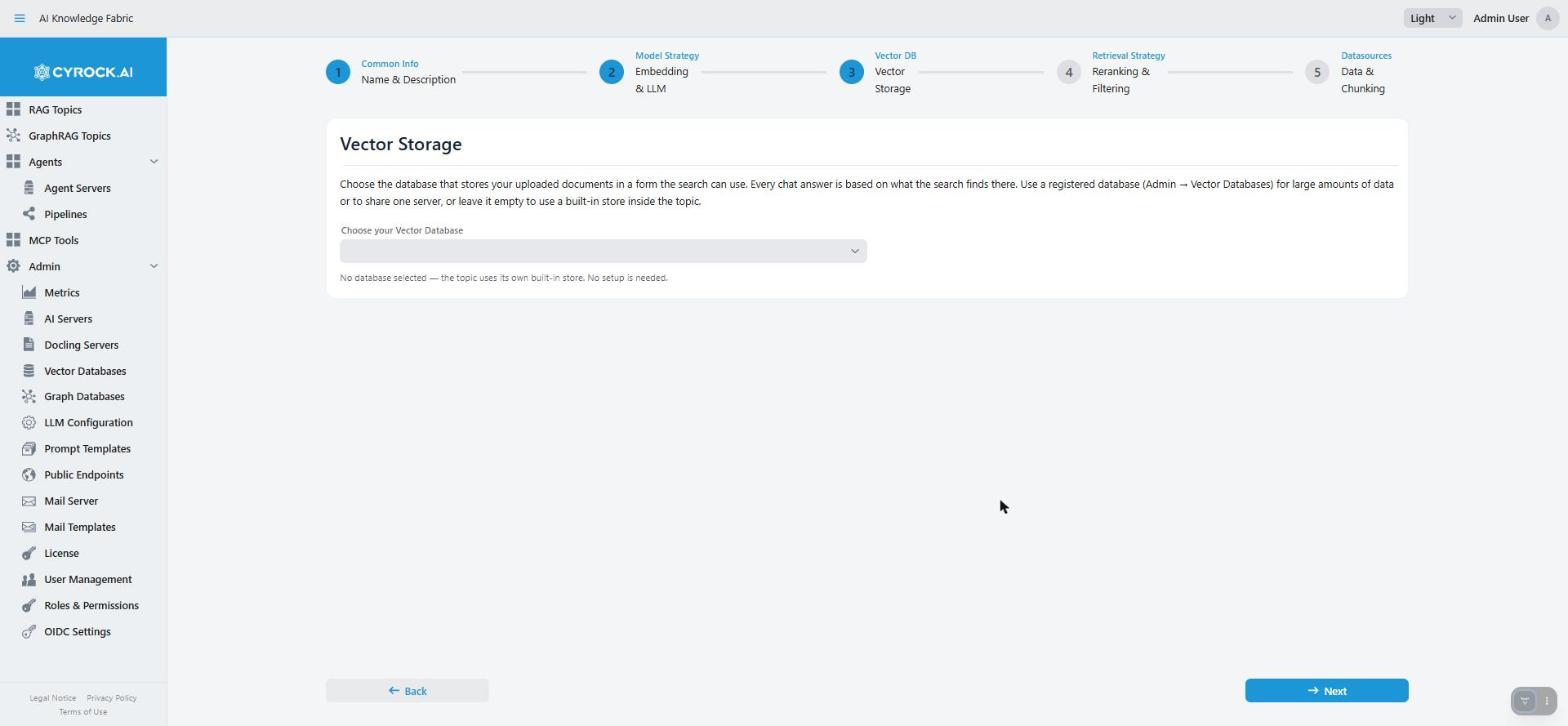
The vector database stores your uploaded documents in a form the search can use. Every chat answer is based on what the search finds there.
One field: Choose your Vector Database. It lists every database from Admin → Vector Databases
as Name (TYPE). After a choice, a line below shows the type, the address and the kind of login.
The field is required. You cannot go to the next step without a database. If the list is empty, no vector database is registered yet, and the step shows a hint to ask an administrator. Several Topics can share one database — each Topic gets its own collection in it. See Connect Vector DB.
|
The vector database cannot be changed after the Topic is created. Decide before you create it. |
Step 4 — Retrieval Strategy
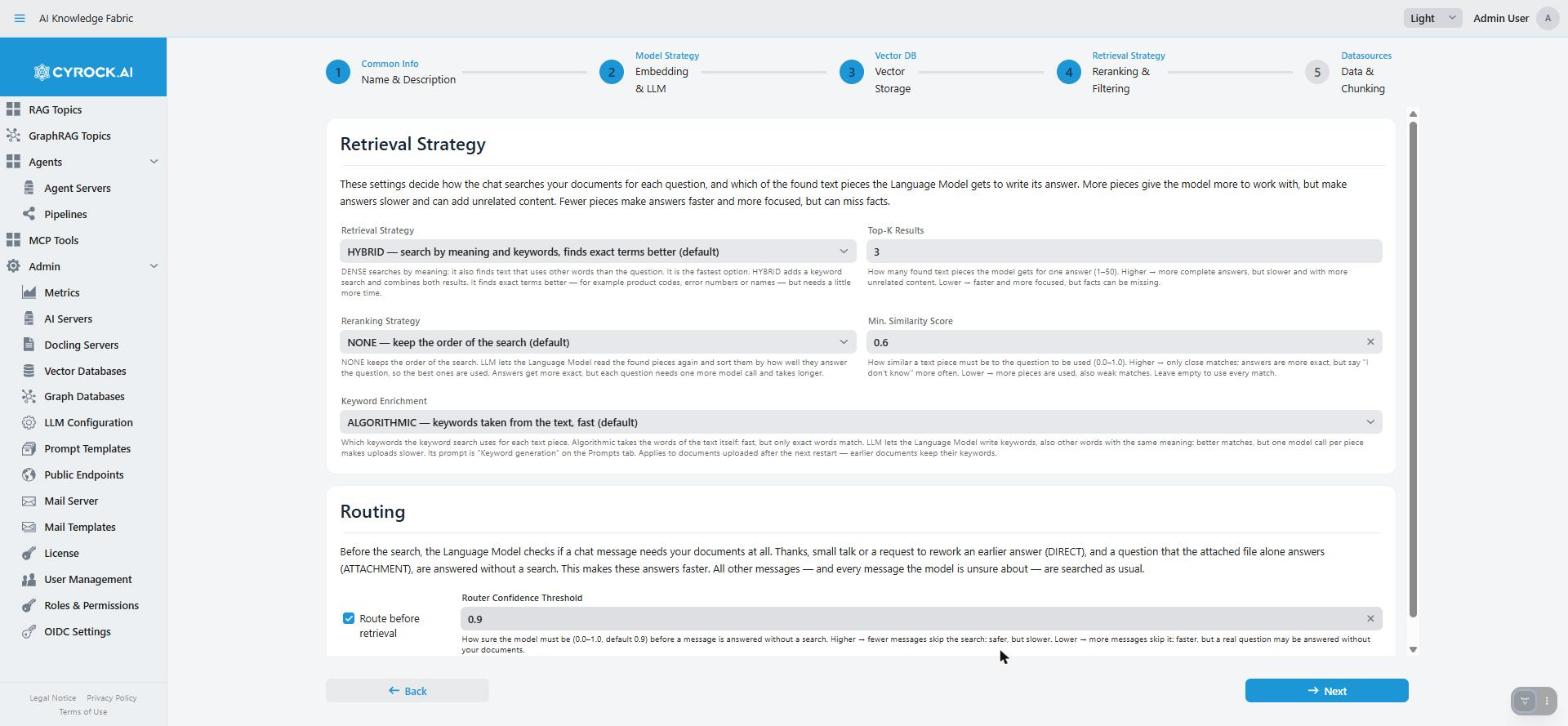
These settings decide how the chat searches your documents for each question, and which found text pieces the Language Model gets for its answer. Every field starts with a working value, so you can go through this step without changes. All of them can be changed later on the Topic’s Configuration tab.
The step has two parts: Retrieval Strategy and Routing.
Retrieval Strategy
| Field | Options / range | Default |
|---|---|---|
Retrieval Strategy |
|
|
Top-K Results |
1–50 |
|
Reranking Strategy |
|
|
Min. Similarity Score |
0.0–1.0, or empty |
|
Keyword Enrichment |
|
|
-
Retrieval Strategy —
DENSEsearches by meaning. It also finds text that uses other words than the question, and it is the fastest option.HYBRIDadds a keyword search and combines both results. It finds exact terms better — for example product codes, error numbers or names — but needs a little more time. -
Top-K Results — how many found text pieces the model gets for one answer. Higher: more complete answers, but slower and with more unrelated content. Lower: faster and more focused, but facts can be missing.
-
Reranking Strategy —
NONEkeeps the order of the search.LLMlets the Language Model read the found pieces again and sort them by how well they answer the question. Answers get more exact, but each question needs one more model call and takes longer. -
Min. Similarity Score — how similar a text piece must be to the question to be used. Higher: only close matches; answers are more exact, but say "I don’t know" more often. Lower: more pieces are used, also weak matches. Leave the field empty to use every match.
-
Keyword Enrichment — only with
HYBRID. It decides which keywords the keyword search uses for each text piece.ALGORITHMICtakes the words of the text itself: fast, but only exact words match.LLMlets the Language Model write keywords, also other words with the same meaning: better matches, but uploads are slower, because each piece needs one model call. Its instructions are "Keyword generation" on the Prompts tab.
Messages you can see: Please select a retrieval strategy, Top-K must be at least 1.
What these settings do to a question, in order:
into numbers"] E --> V["2 · Search
(DENSE or HYBRID)"] V --> R["3 · Optional
LLM reranking"] R --> M["4 · Drop pieces below
the minimum score"] M --> A["Top-K pieces
→ answer"]
The defaults are a good start. Then adjust:
-
Answers miss content that is clearly in the documents → raise Top-K, or lower the minimum score.
-
Answers bring in unrelated content → raise the minimum score, or switch reranking to
LLM. -
Answers are slow or expensive → lower Top-K, and keep reranking at
NONE.
Routing
Before the search, the Language Model checks if a chat message needs your documents at all. Thanks, small talk or a request to rework an earlier answer, and a question that an attached file alone answers, are answered without a search. This makes these answers faster. All other messages — and every message the model is unsure about — are searched as usual.
| Field | Default | Notes |
|---|---|---|
Route before retrieval |
on |
On: messages that need no search are answered faster. Off: every message searches your documents — one model call less per message, but small talk is slower |
Router Confidence Threshold |
|
0.0–1.0. Only active while routing is on |
Router Confidence Threshold is how sure the model must be before a message is answered without a search. Higher: fewer messages skip the search — safer, but slower. Lower: more messages skip it — faster, but a real question may be answered without your documents. While routing is on, the field must not be empty; otherwise the message is Enter a value between 0.0 and 1.0.
Step 5 — Datasources
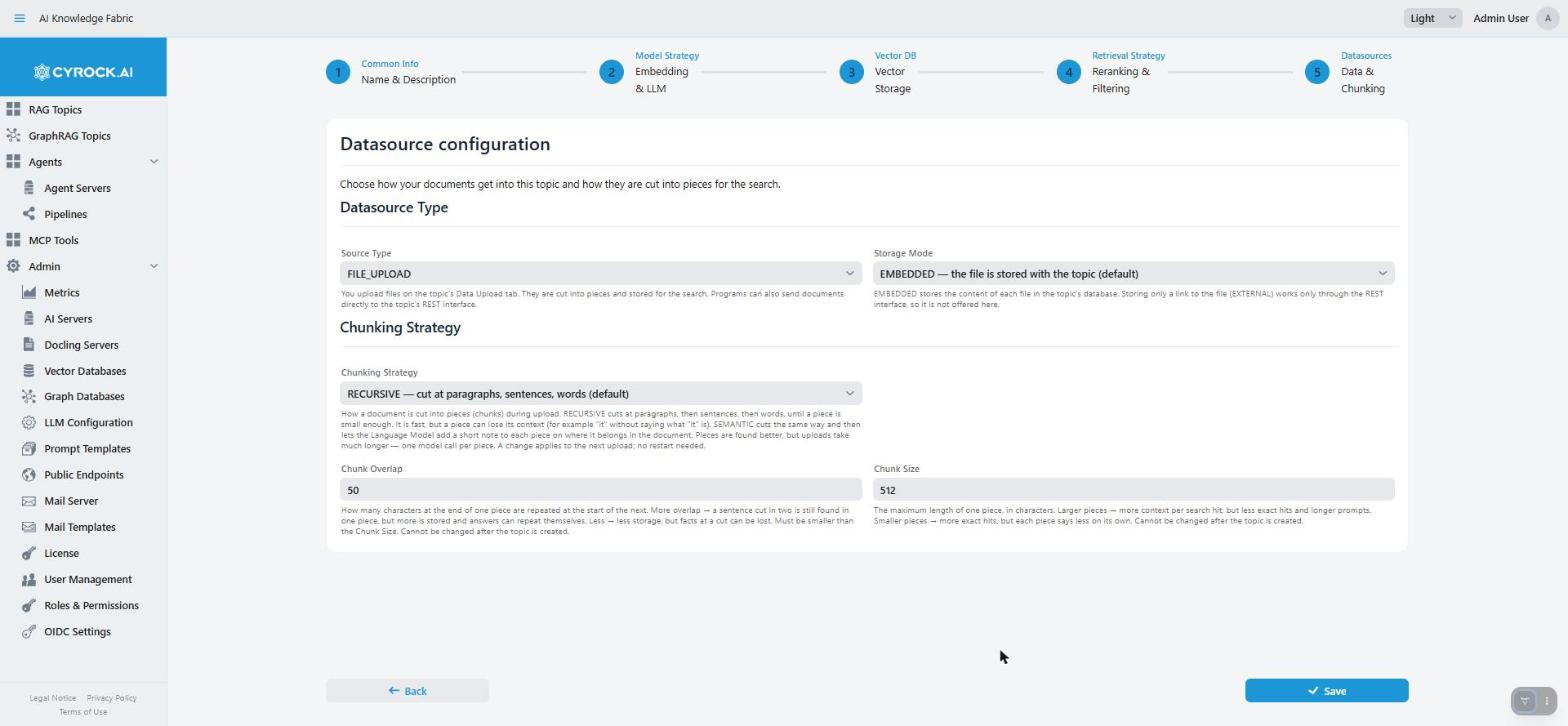
This step decides how documents get into the Topic and how they are cut into pieces (chunks) for the search. You upload the files later, on the Topic’s Data Upload tab.
| Field | Default | Notes |
|---|---|---|
Source Type |
|
The only option. Programs can also send documents to the Topic’s REST interface |
Storage Mode |
|
The only option. The content of each file is stored in the Topic’s database |
Chunking Strategy |
|
How a document is cut into pieces — see below |
Chunk Size |
|
Maximum length of one piece, in characters |
Chunk Overlap |
|
Characters at the end of one piece that are repeated at the start of the next. Must be smaller than the Chunk Size |
-
Chunk Size — larger pieces: more context per search hit, but less exact hits and longer prompts. Smaller pieces: more exact hits, but each piece says less on its own.
-
Chunk Overlap — more overlap: a sentence cut in two is still found in one piece, but more is stored and answers can repeat themselves. Less overlap: less storage, but facts at a cut can be lost.
|
Chunk Size and Chunk Overlap cannot be changed after the Topic is created. The Chunking Strategy can: it applies from the next upload on, with no restart. |
Messages you can see: Chunk Size must be at least 1, Chunk Overlap must not be negative, Chunk Overlap must be smaller than Chunk Size.
Storing only a link to each file (EXTERNAL) works only through the REST interface, so the wizard does
not offer it.
The two chunking strategies
| Strategy | What happens | Cost |
|---|---|---|
|
Cuts at paragraphs, then sentences, then words, until a piece is small enough |
Fast |
|
Cuts the same way. Then the Language Model adds a short note to each piece on where it belongs in the document |
One model call per piece — uploads take much longer |
(+ model note if SEMANTIC)"] S1 --> S2["2 · Turn each piece
into numbers"] S2 --> S3["3 · Store"] S3 --> D["Document can be found"]
With RECURSIVE, a piece can lose its context, for example "it" without saying what "it" is. Choose
SEMANTIC when a piece means little on its own — a table row, a numbered clause, a paragraph that
refers to something named pages earlier. Despite the name, it does not cut by meaning. It improves
what each piece says about itself. Try it on a few documents first.
After saving
The Topic appears in the list with status CREATED. To use it:
-
Start it (requires
TOPIC_START). The status goesSTARTING→RUNNING. The first start can take longer, because the Topic’s software is downloaded first. -
Upload documents on the Data Upload tab and click Start Embedding.
-
Chat: click the Topic name in the list (only while it is
RUNNING, and withTOPIC_CHAT).
Troubleshooting
| Symptom | Cause and fix |
|---|---|
New Topic button missing |
You don’t have the |
Message after clicking New Topic |
No valid license, or the license’s Topic limit is reached. See Admin → License |
Next does nothing on step 2 |
A required choice is missing: embedding model, Language Model, Docling server, or the picture model. Scroll down — a red message names it |
Next does nothing on step 3, or the vector database list is empty |
A vector database is required. If the list is empty, ask an administrator to register one under Admin → Vector Databases |
Docling part appeared unexpectedly |
Documents is ticked among the File Types, or Allow binary documents as chat attachments is on. Both need a Docling server |
Describe pictures with a vision model cannot be unticked |
Images is a File Type. Remove it to unlock the box |
Show pictures in answers is greyed out |
Store pictures in the database is off |
Model dialog shows a Model ID field instead of a list |
No model list is available for that server. Check it under Admin → AI Servers, click Refresh, or enter the model by hand |
A new model is missing from the list |
The list is a stored copy. Click Refresh in the dialog |
Topic goes to |
Docker cannot be reached, or the port is already used by another program or Topic |
Name changed while typing |
Spaces become underscores automatically |
No template buttons above Custom System Prompt |
No templates exist. Create them under Admin → Prompt Templates |
Chat refuses an image attachment |
Allow images as chat attachments is off, or the Language Model cannot read images |
Related
-
Getting Started — this wizard in the context of the whole path, from installation to first chat